Claude Chat Completion API Application and Usage
Anthropic Claude is a very powerful AI conversational system. Simply by entering prompts, it can generate fluent and natural responses in just a few seconds. Claude stands out in the industry for its outstanding language understanding and generation capabilities. Today, Claude has already been widely used across various industries and fields, with its influence becoming increasingly significant. Whether for daily conversations, creative writing, professional consultation, or code programming, Claude can provide astonishing intelligent assistance, greatly improving human work efficiency and creativity.
This document mainly introduces the usage process of Claude Chat Completion API operations. With it, we can easily use the conversation features of the official Claude.
¶ Application Process
To use the Claude Chat Completion API, first go to the WorldAi Console to obtain your API Token and keep it for later use.

If you have not logged in or registered yet, you will be automatically redirected to the login page and invited to register and log in. After completion, you will automatically return to the current page.
One API Token can call all platform services; there is no need to apply separately for each service. Your first application will include free credits for a free trial; when credits are insufficient, you can top up your general balance in the Console.
📘 Full documentation: Claude Chat Completion API →
¶ Basic Usage
Next, you can fill in the corresponding content in the interface, as shown in the figure:
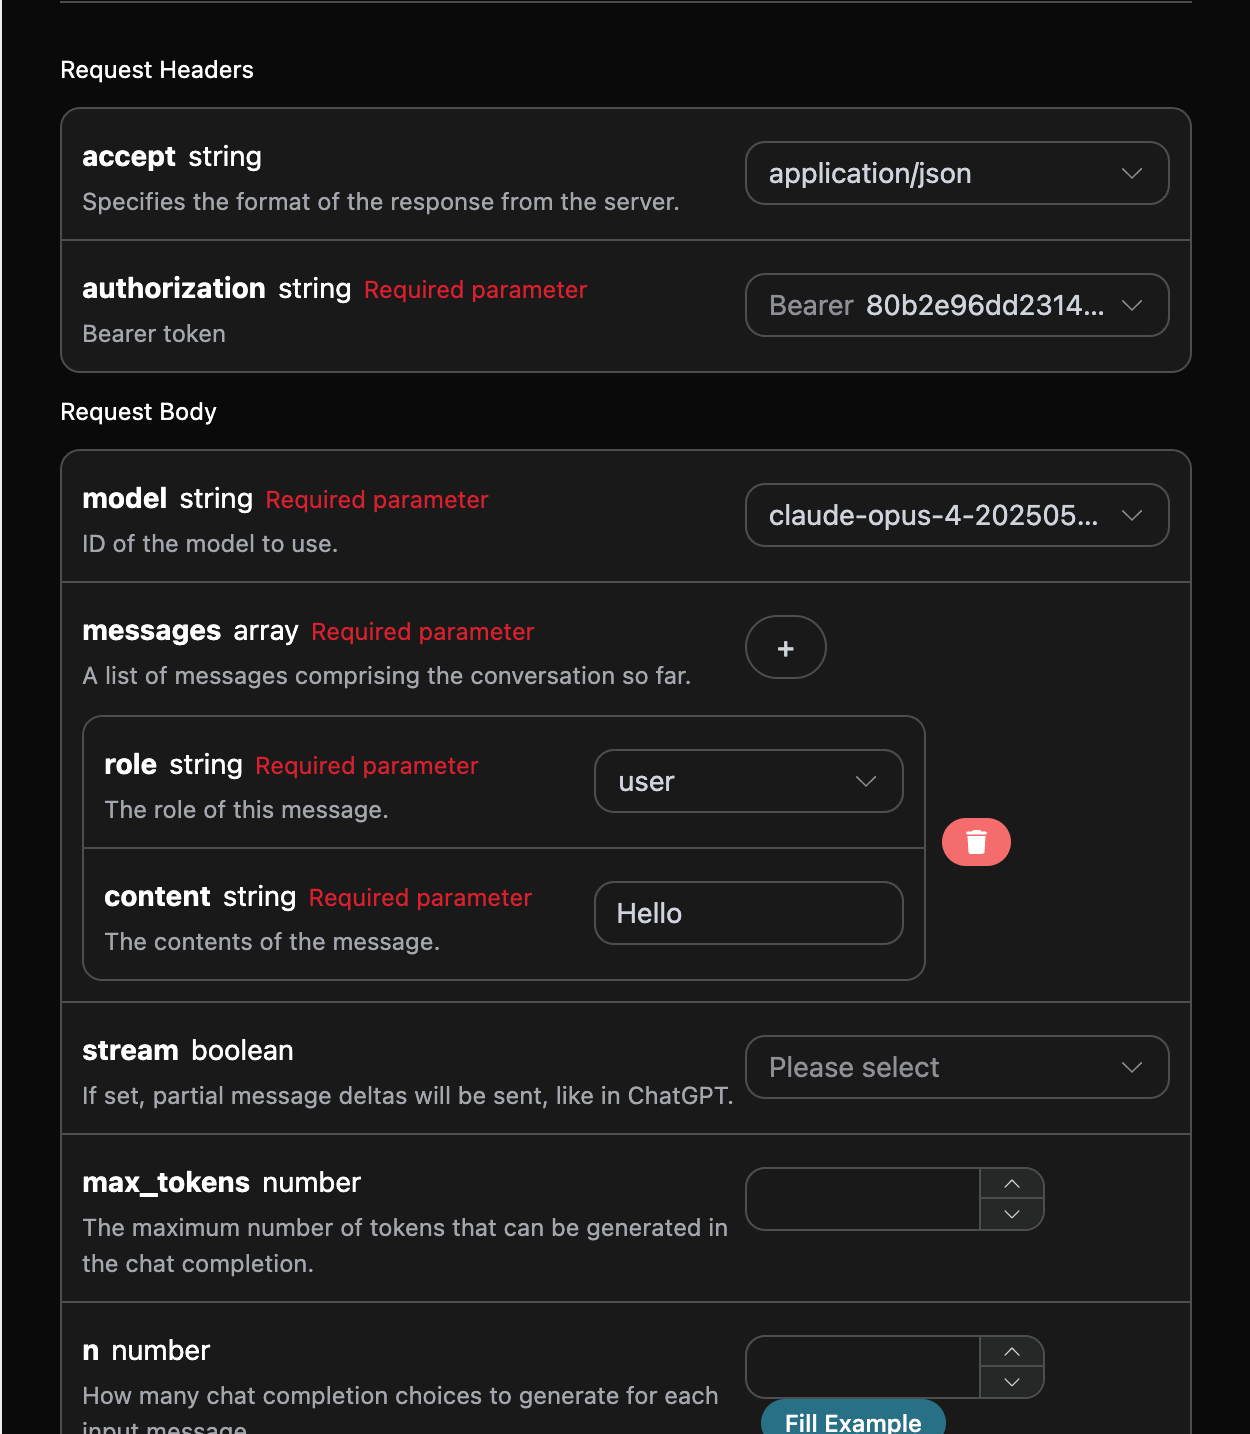
When using this API for the first time, we need to fill in at least three items. One is authorization, which can be selected directly from the dropdown list. Another parameter is model, where you can select public models such as claude-opus-5-5 and claude-fable-5-1; the original claude-fable-5 can still continue to be called. The final parameter is messages, which is an array of prompts, with each element containing role and content; role supports user, assistant, and system, while content is the specific content. If you need complete Claude thinking content blocks, signatures, and native tool semantics, please continue to use the Messages API.
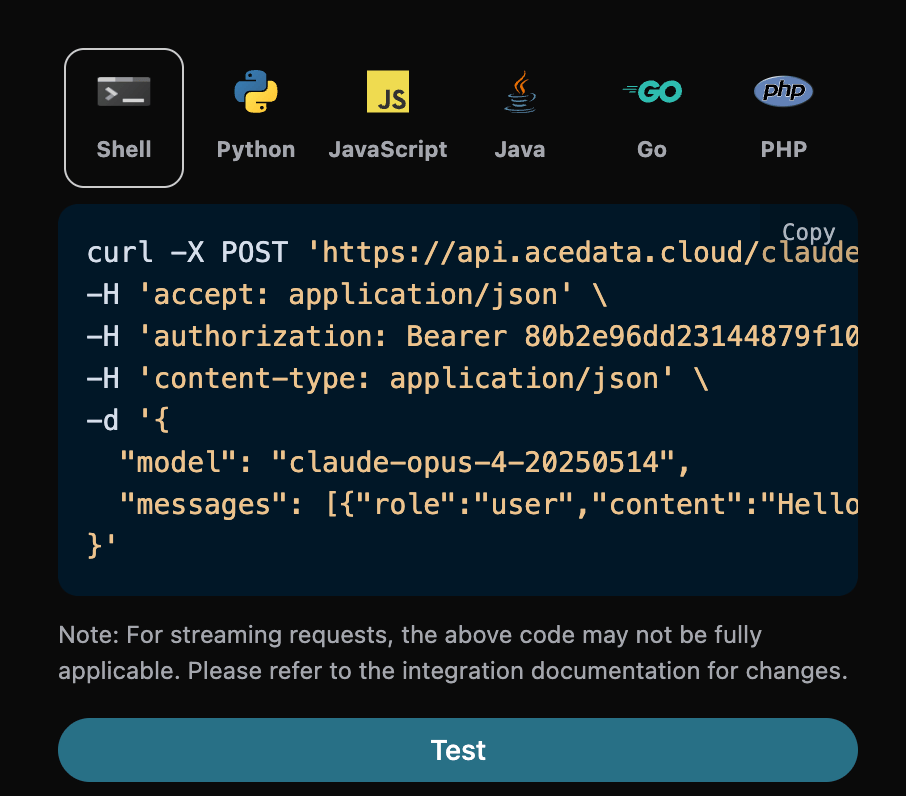
At the same time, you can notice that corresponding call code is generated on the right. You can copy the code and run it directly, or click the “Try” button directly for testing.
Common optional parameters:
max_tokens: Limits the maximum number of tokens in a single response.temperature: Generation randomness, between 0 and 2; the larger the value, the more divergent it is.n: How many candidate responses to generate at once.response_format: Response format settings.
claude-opus-5-5 supports both regular and streaming Chat Completions; this model only allows n=1. Do not set its temperature below 1 or use a non-default top_p; for tool calls, use tool_choice: "auto" and do not force a specific tool. The Chat-compatible API does not return native thinking content blocks.
After calling it, we find that the returned result is as follows:
{
  "id": "msg_bdrk_01Q6WN27v95ypCa1kbanAQ6K",
  "model": "claude-opus-4-8",
  "object": "chat.completion",
  "created": 1768619365,
  "choices": [
    {
      "index": 0,
      "message": {
        "role": "assistant",
        "content": "Hello! How can I help you today?"
      },
      "finish_reason": "stop"
    }
  ],
  "usage": {
    "prompt_tokens": 8,
    "completion_tokens": 12,
    "total_tokens": 20,
    "prompt_tokens_details": {
      "cached_tokens": 0,
      "cache_write_tokens": 0
    },
    "completion_tokens_details": {
      "reasoning_tokens": 0
    }
  }
}
The returned result contains multiple fields, introduced as follows:
id, the ID generated for this conversation task, used to uniquely identify this conversation task.model, the selected Claude official website model.choices, the response information provided by Claude for the prompt.usage: Statistics on tokens for this Q&A session.
In the Chat Completions format, usage.prompt_tokens is the total input amount; prompt_tokens_details.cached_tokens and prompt_tokens_details.cache_write_tokens record cache read and write details respectively. completion_tokens_details.reasoning_tokens is a subset of completion_tokens; do not add it again when calculating totals or costs. Non-streaming responses may also return a usage.cost object, where amount is the actual credit consumption, currency is the unit of measurement, and list_amount is the amount before discounts, if applicable.
The field name for Chat-compatible is reasoning_tokens; the native Messages API uses output_tokens_details.thinking_tokens. The wire schemas of the two protocols are different, and clients should not mix field names.
Among them, choices contains Claude's response information, and the choices inside it contains the specific information of Claude's response, as shown in the figure.
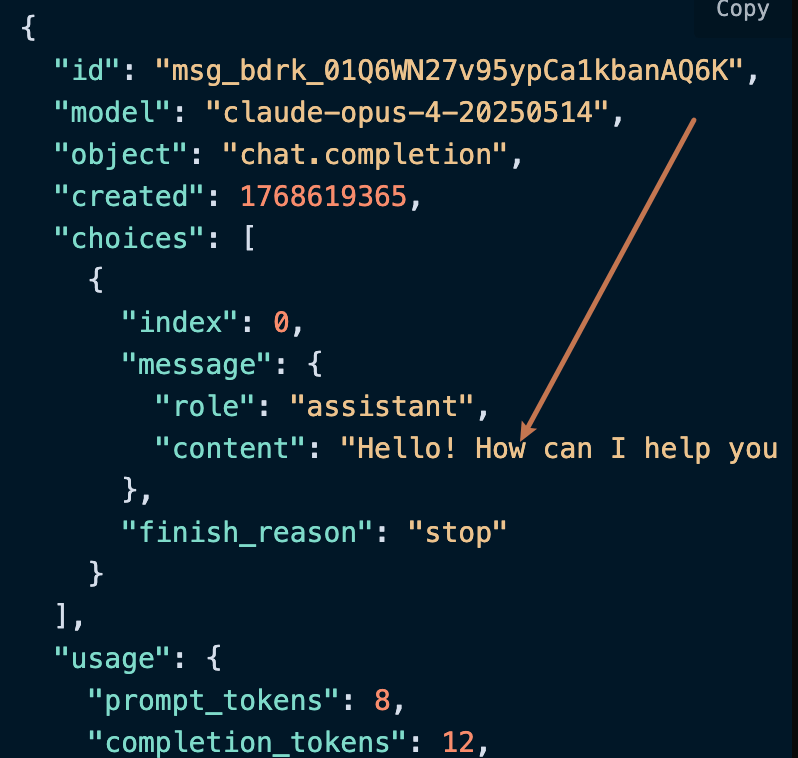
As you can see, the content field inside choices contains the specific content of Claude's reply.
¶ Streaming Response
This API also supports streaming responses, which is very useful for web integration and can enable a webpage to display text character by character.
If you want to return responses in a stream, you can change the stream parameter in the request header to true.
The modification is shown in the figure, but the call code also needs corresponding changes to support streaming responses.
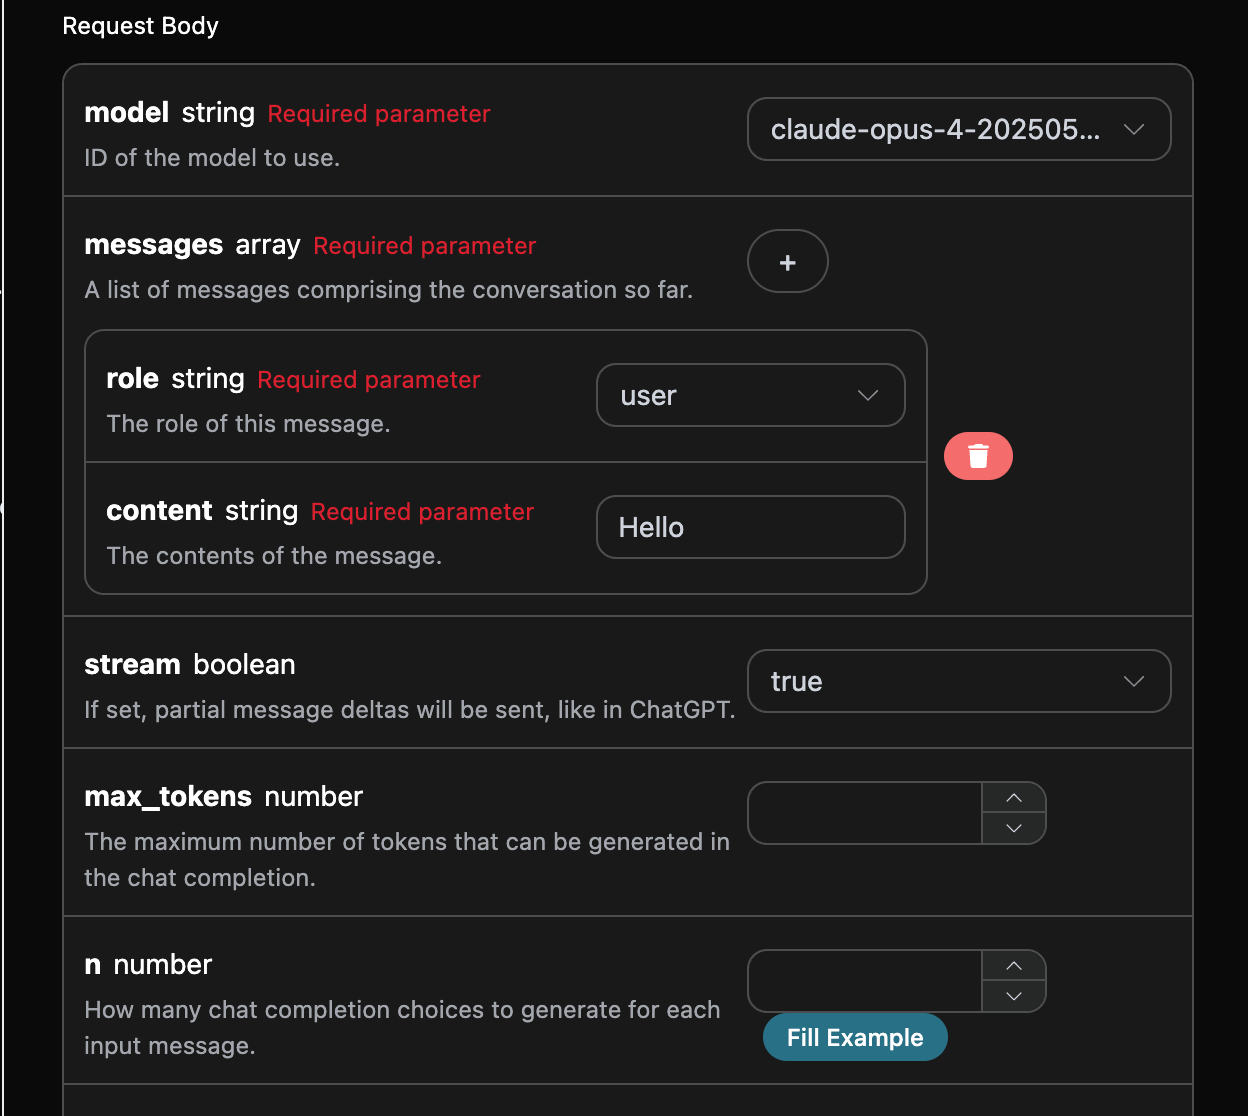
After changing stream to true, the API will return the corresponding JSON data line by line. At the code level, we need to make corresponding changes to obtain the line-by-line results.
Python sample call code:
import requests

url = "https://api.worldai.chat/v1/chat/completions"

headers = {
    "accept": "application/json",
    "authorization": "Bearer {token}",
    "content-type": "application/json"
}

payload = {
    "model": "claude-opus-4-20250514",
    "messages": [{"role":"user","content":"Hello"}],
    "stream": True
}

response = requests.post(url, json=payload, headers=headers)
print(response.text)
The output effect is as follows:
data: {"id": "msg_bdrk_01LPPqDjLKMgfSwTRMRty9VT", "object": "chat.completion.chunk", "created": 1768619445, "model": "claude-opus-4-20250514", "system_fingerprint": null, "choices": [{"delta": {"content": "", "role": "assistant"}, "logprobs": null, "finish_reason": null, "index": 0}], "usage": null}

data: {"id": "msg_bdrk_01LPPqDjLKMgfSwTRMRty9VT", "object": "chat.completion.chunk", "created": 1768619445, "model": "claude-opus-4-20250514", "system_fingerprint": null, "choices": [{"delta": {"content": ""}, "logprobs": null, "finish_reason": null, "index": 0}], "usage": null}

data: {"id": "msg_bdrk_01LPPqDjLKMgfSwTRMRty9VT", "object": "chat.completion.chunk", "created": 1768619445, "model": "claude-opus-4-20250514", "system_fingerprint": null, "choices": [{"delta": {"content": "Hello!"}, "logprobs": null, "finish_reason": null, "index": 0}], "usage": null}

data: {"id": "msg_bdrk_01LPPqDjLKMgfSwTRMRty9VT", "object": "chat.completion.chunk", "created": 1768619445, "model": "claude-opus-4-20250514", "system_fingerprint": null, "choices": [{"delta": {"content": " How can I help you"}, "logprobs": null, "finish_reason": null, "index": 0}], "usage": null}

data: {"id": "msg_bdrk_01LPPqDjLKMgfSwTRMRty9VT", "object": "chat.completion.chunk", "created": 1768619445, "model": "claude-opus-4-20250514", "system_fingerprint": null, "choices": [{"delta": {"content": " today?"}, "logprobs": null, "finish_reason": null, "index": 0}], "usage": null}

data: {"id": "msg_bdrk_01LPPqDjLKMgfSwTRMRty9VT", "object": "chat.completion.chunk", "created": 1768619445, "model": "claude-opus-4-20250514", "system_fingerprint": null, "choices": [{"delta": {}, "logprobs": null, "finish_reason": "stop", "index": 0}], "usage": null}

data: {"id": "msg_bdrk_01LPPqDjLKMgfSwTRMRty9VT", "object": "chat.completion.chunk", "created": 1768619445, "model": "claude-opus-4-20250514", "system_fingerprint": null, "choices": [], "usage": {"prompt_tokens": 8, "completion_tokens": 12, "total_tokens": 20, "prompt_tokens_details": {"cached_tokens": 0, "cache_write_tokens": 0}, "completion_tokens_details": {"reasoning_tokens": 0}}}

data: [DONE]
It can be seen that there are many data entries in the response. The choices within data are the latest response content, which is consistent with the content introduced above. choices contains the newly added response content, and you can integrate it into your system based on the results. At the same time, the end of the streaming response is determined based on the content of data. If the content is [DONE], it indicates that the streaming response has completely ended. The returned data result contains multiple fields, which are introduced as follows:
id, the ID generated for this conversation task, used to uniquely identify this conversation task.model, the selected Claude official website model.choices, the response information provided by Claude for the prompt.
JavaScript is also supported. For example, the Node.js streaming invocation code is as follows:
const options = {
  method: "post",
  headers: {
    accept: "application/json",
    authorization: "Bearer {token}",
    "content-type": "application/json",
  },
  body: JSON.stringify({
    model: "claude-opus-4-20250514",
    messages: [{ role: "user", content: "Hello" }],
    stream: true,
  }),
};

fetch("https://api.worldai.chat/v1/chat/completions", options)
  .then((response) => response.json())
  .then((response) => console.log(response))
  .catch((err) => console.error(err));
Java sample code:
JSONObject jsonObject = new JSONObject();
jsonObject.put("model", "claude-opus-4-20250514");
jsonObject.put("messages", [{"role":"user","content":"Hello"}]);
jsonObject.put("stream", true);
MediaType mediaType = "application/json; charset=utf-8".toMediaType();
RequestBody body = jsonObject.toString().toRequestBody(mediaType);
Request request = new Request.Builder()
  .url("https://api.worldai.chat/v1/chat/completions")
  .post(body)
  .addHeader("accept", "application/json")
  .addHeader("authorization", "Bearer {token}")
  .addHeader("content-type", "application/json")
  .build();

OkHttpClient client = new OkHttpClient();
Response response = client.newCall(request).execute();
System.out.print(response.body!!.string())
Other languages can be adapted separately. The principle is the same.
¶ Multi-turn Conversation
If you want to integrate multi-turn conversation functionality, you need to upload multiple prompts in the messages field. A specific example of multiple prompts is shown in the image below:
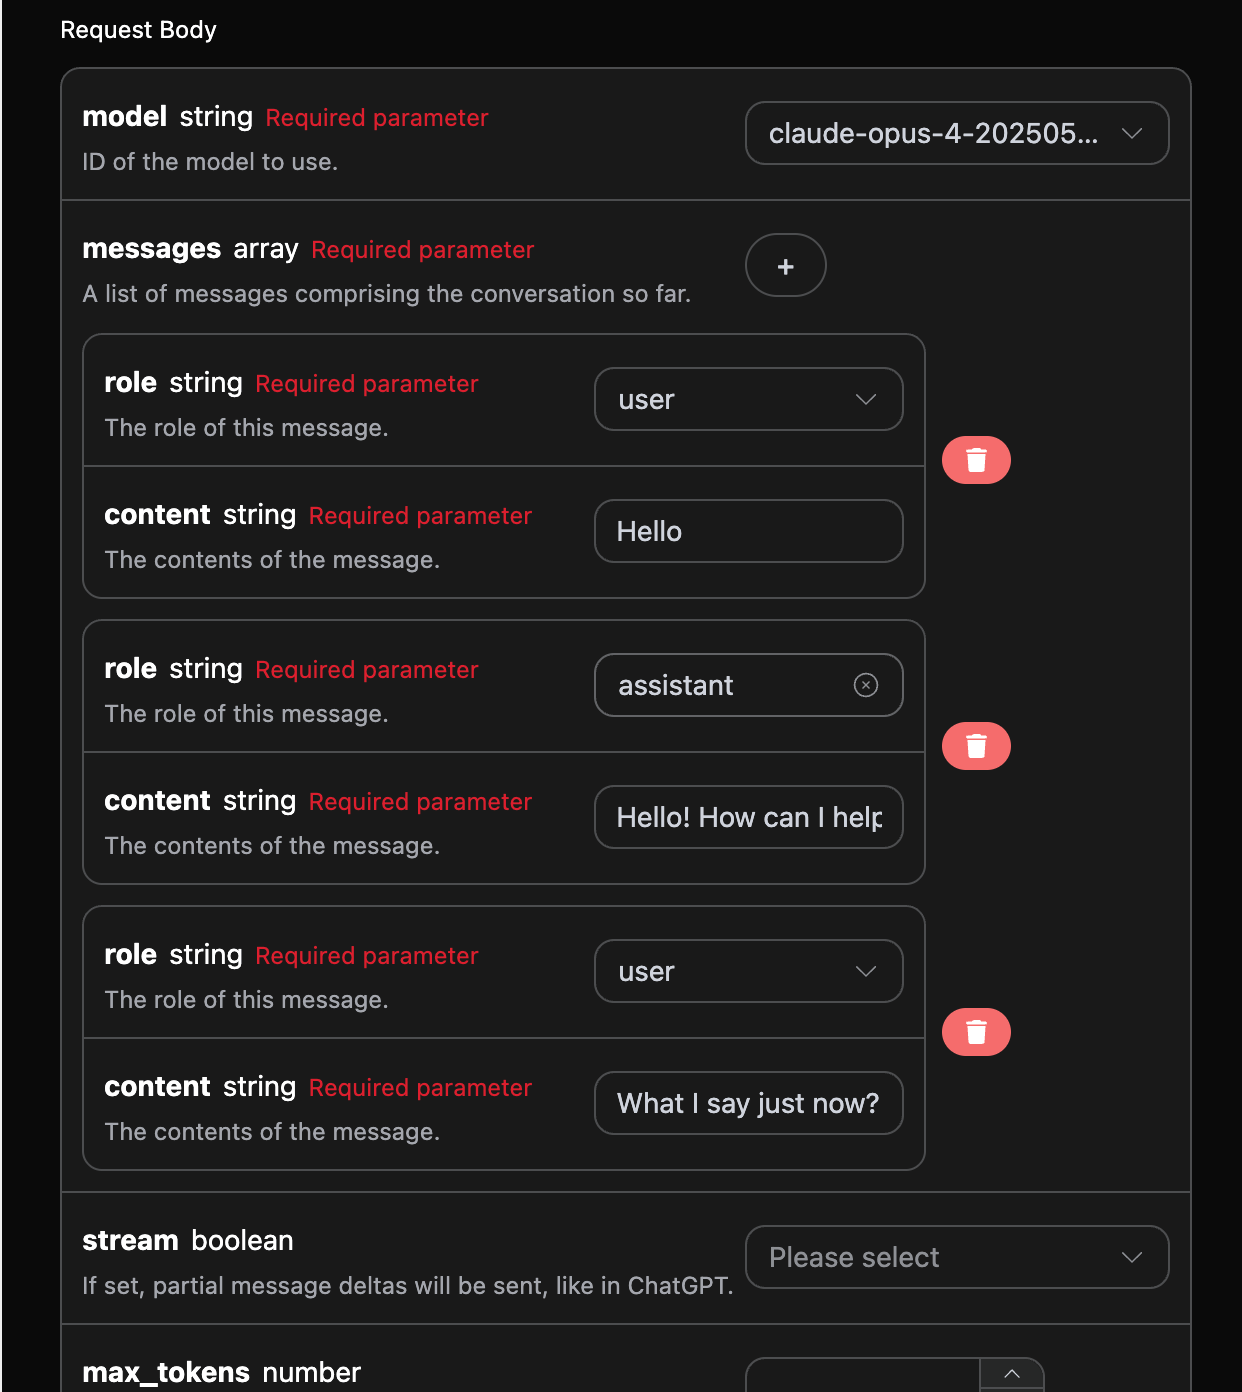
Python sample invocation code:
import requests

url = "https://api.worldai.chat/v1/chat/completions"

headers = {
    "accept": "application/json",
    "authorization": "Bearer {token}",
    "content-type": "application/json"
}

payload = {
    "model": "claude-opus-4-20250514",
    "messages": [{"role":"user","content":"Hello"},{"role":"assistant","content":"Hello! How can I help you today?"},{"role":"user","content":"What I say just now?"}]
}

response = requests.post(url, json=payload, headers=headers)
print(response.text)
By uploading multiple prompts, multi-turn conversations can be easily implemented, and the following response can be obtained:
{
  "id": "msg_bdrk_01Y1wfQmd89g968TVbFu57Yc",
  "model": "claude-opus-4-20250514",
  "object": "chat.completion",
  "created": 1768619674,
  "choices": [
    {
      "index": 0,
      "message": {
        "role": "assistant",
        "content": "You said \"Hello\" - that was your first message to me in our conversation."
      },
      "finish_reason": "stop"
    }
  ],
  "usage": {
    "prompt_tokens": 29,
    "completion_tokens": 20,
    "total_tokens": 49,
    "prompt_tokens_details": {
      "cached_tokens": 0,
      "cache_write_tokens": 0
    },
    "completion_tokens_details": {
      "reasoning_tokens": 0
    }
  }
}
It can be seen that the information contained in choices is consistent with the basic usage content. This contains the specific content of Claude's replies to multiple conversations, so that corresponding questions can be answered based on multiple conversation contents.
¶ Deep Thinking
New-generation Claude models may reason according to the model's default strategy, without needing to be triggered through the -thinking model suffix. Chat-compatible responses use the OpenAI-compatible usage field completion_tokens_details.reasoning_tokens. reasoning_tokens is already included in completion_tokens; do not add them again. Reasoning and visible text share the output token limit, so when max_tokens is small, the text may be empty or truncated; in this case, increase the output budget, or select a lower reasoning effort when supported by the model you are using.
If you need native thinking, output_config.effort, thinking content blocks, and signature return, please use /v1/messages. The corresponding usage field for Messages is output_tokens_details.thinking_tokens; do not mix it with Chat-compatible completion_tokens_details.reasoning_tokens.
¶ Vision Models
claude-sonnet-4-20250514 is a multimodal large language model developed by Claude. It adds visual understanding capabilities based on claude-4. This model can process both text and image inputs simultaneously, enabling cross-modal understanding and generation.
The text processing of the claude-sonnet-4-20250514 model is consistent with the basic usage described above. Below is a brief introduction to how to use the model's image processing capabilities.
The image processing capability of the claude-sonnet-4-20250514 model is mainly enabled by adding a type field to the original content content. Through this field, it can determine whether the upload is text or an image, thereby using the image processing capability of the claude-sonnet-4-20250514 model. The following mainly describes how to call this feature using Curl and Python.
- Curl script method
curl -X POST 'https://api.worldai.chat/v1/chat/completions' \
-H 'accept: application/json' \
-H 'authorization: Bearer {token}' \
-H 'content-type: application/json' \
-d '{
    "model": "claude-sonnet-4-20250514",
    "messages": [
      {
        "role": "user",
        "content": [
          {
            "type": "text",
            "text": "What'\''s in this image?"
          },
          {
            "type": "image_url",
            "image_url": {
              "url": "https://cdn.acedata.cloud/ueugot.png"
            }
          }
        ]
      }
    ]
  }'
- Python script method
import requests

url = "https://api.worldai.chat/v1/chat/completions"

headers = {
    "accept": "application/json",
    "authorization": "Bearer {token}",
    "content-type": "application/json"
}

payload = {
    "model": "claude-sonnet-4-20250514",
    "messages": [
        {
            "role": "user",
            "content": [
                {
                    "type": "text", "text": "What's in this image?"
                },
                {
                    "type": "image_url",
                    "image_url": {
                        "url": "https://cdn.acedata.cloud/ueugot.png"
                    }
                },
            ],
        }
    ]
}

response = requests.post(url, json=payload, headers=headers)
print(response.text)
Then you can obtain the following result. The field information in the result is consistent with the above; the details are as follows:
{
  "id": "msg_bdrk_01NCrxpZmV17bhQJJRQEFEb9",
  "model": "claude-sonnet-4-20250514",
  "object": "chat.completion",
  "created": 1768628904,
  "choices": [
    {
      "index": 0,
      "message": {
        "role": "assistant",
        "content": "This image shows an API request configuration interface for what appears to be an AI chat completion service. Here are the key elements:\n\n**Request Body Parameters:**\n\n1. **model** (required string) - Set to \"claude-opus-4-202505...\" - specifies which AI model to use\n\n2. **messages** (required array) - Contains the conversation history with:\n   - **role** (required string) - Set to \"user\" \n   - **content** (required string) - Contains \"Hello\" as the message content\n\n3. **stream** (boolean) - Set to \"true\" - enables partial message deltas like in ChatGPT\n\n4. **max_tokens** (number) - Field for setting maximum tokens that can be generated in the response\n\n5. **n** (number) - Specifies how many chat completion choices to generate for each input\n\nThe interface has a dark theme with white text on black/dark gray backgrounds. There's a \"Fill Example\" button at the bottom right and various dropdown menus and input fields for configuring the API request parameters. A red trash/delete icon is visible, likely for removing message entries."
      },
      "finish_reason": "stop"
    }
  ],
  "usage": {
    "prompt_tokens": 1570,
    "completion_tokens": 252,
    "total_tokens": 1822,
    "prompt_tokens_details": {
      "cached_tokens": 0,
      "cache_write_tokens": 0
    },
    "completion_tokens_details": {
      "reasoning_tokens": 0
    }
  }
}
It can be seen that the answer is based on the image. Therefore, through the above two methods, you can easily use the text and image processing capabilities of the claude-3-7-sonnet-20250219 model.
¶ Error Handling
When calling the API, if an error occurs, the API will return the corresponding error code and information. For example:
400 token_mismatched: Bad request, possibly due to missing or invalid parameters.400 api_not_implemented: Bad request, possibly due to missing or invalid parameters.401 invalid_token: Unauthorized, invalid or missing authorization token.429 too_many_requests: Too many requests, you have exceeded the rate limit.500 api_error: Internal server error, something went wrong on the server.
¶ Error Response Example
{
  "success": false,
  "error": {
    "code": "api_error",
    "message": "fetch failed"
  },
  "trace_id": "2cf86e86-22a4-46e1-ac2f-032c0f2a4e89"
}
¶ Conclusion
Through this document, you have learned how to easily implement the official Claude conversation functionality using the Claude Chat Completion API. We hope this document can help you better integrate and use this API. If you have any questions, please feel free to contact our technical support team.